Building Minds
Measuring Neuroplasticity in an Institutional Decision Memory
Dr. Jerry A. Smith · August 19, 2026 · 12 min read
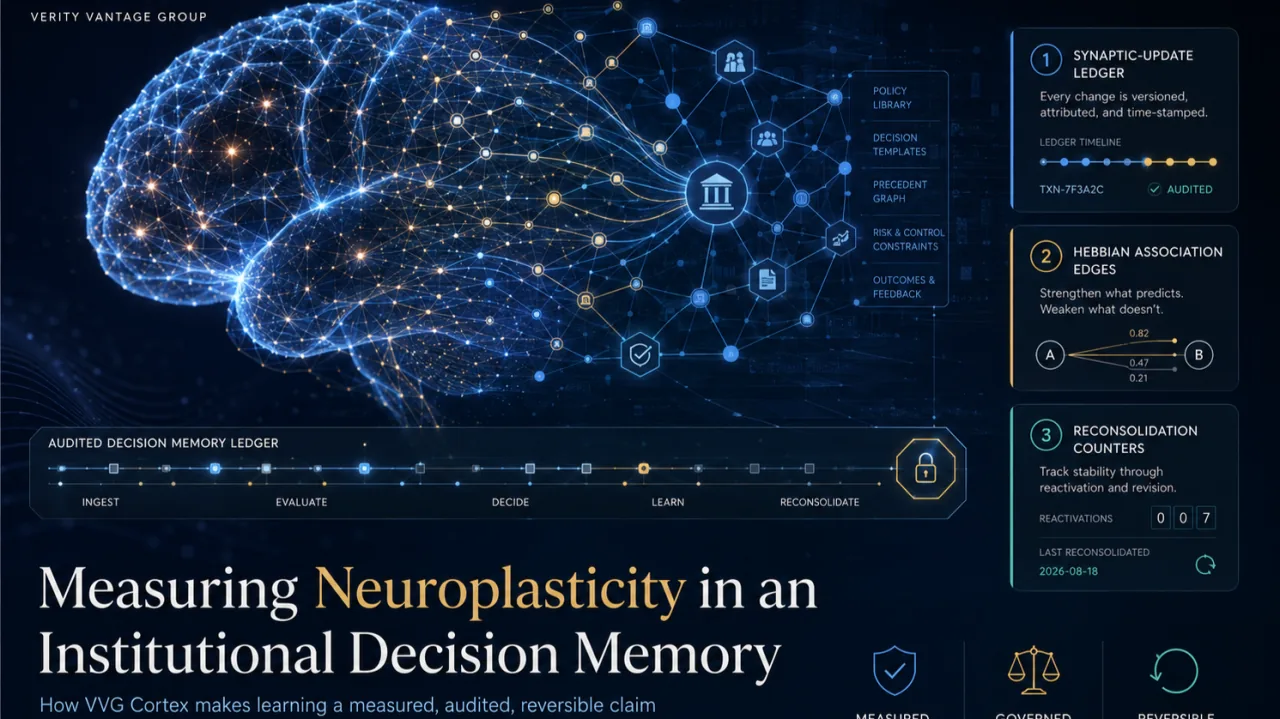
How VVG Cortex makes “the system learns” a measured, audited, reversible claim.
Abstract
VVG Cortex is an institutional decision-memory system built structures-down from the brain's neurocognitive characteristics: a hippocampal record (episodic and semantic stores, consolidation) under cortical control (attention, valuation, executive function), with a dopaminergic learning loop (reward prediction error driving bounded plasticity). A system designed this way must eventually answer the question every agentic system now faces: if it changes with experience, how do you know what changed, why, and by how much? Our answer borrows from neuroscience twice over — once for the mechanisms of plasticity, and once for the discipline of measuring it. This paper describes the brain’s plasticity and how neuroscience measures it; why measurement, not plasticity itself, is the load-bearing idea; and how Cortex implements the analog: a synaptic-update ledger for parametric plasticity, Hebbian association edges for structural plasticity, and reconsolidation counters for trace-level plasticity — each bounded, evidence-gated, and readable as a set of metrics. The result is a system whose learning is not a marketing claim but a queryable record, and whose users can see, for any answer, what experience shaped it.
What is the brain, for our purposes?
Strip the brain to the properties an engineer must respect, and three remain. First, it is a memory that acts: roughly 86 billion neurons whose usefulness lies not in the units but in the ~10¹⁴ synaptic connections among them, organized into systems that store (hippocampus, neocortex), evaluate (orbitofrontal and ventromedial prefrontal cortex, amygdala), attend (salience network, locus coeruleus), and control (dorsolateral prefrontal cortex). Second, it is modulated: what it stores is relatively stable, but how strongly things are connected and what gets processed changes continuously with experience. Third — and this is the property this paper is about — it is plastic within bounds. Donald Hebb’s 1949 postulate (“cells that fire together wire together”) describes the mechanism; the Bienenstock–Cooper–Munro sliding threshold and Turrigiano’s homeostatic synaptic scaling describe the constraint: a brain whose weights could move without limit would seize (runaway potentiation) or forget everything (runaway depression). Plasticity is useful precisely because it is bounded, slow relative to activity, and biased by a teaching signal.
That teaching signal has a name and an anatomy. Schultz, Dayan, and Montague showed that midbrain dopamine neurons encode reward prediction error — not reward, but the difference between expected and received. Prediction error is what turns raw experience into a direction of change: strengthen what did better than expected, weaken what did worse. Every modern account of biological learning — and, not coincidentally, of machine learning — runs through this quantity.
So a memory that acts, modulated by attention and value, changed by prediction error, within homeostatic bounds. That is the brain we set out to mirror, and it is also the checklist for what a faithful measurement program must capture.
How does neuroscience measure neuroplasticity?
Neuroscience cannot yet watch every synapse, so it measures plasticity at several levels at once, and the multi-level habit is the methodological lesson.
Synaptic (functional) level. The canonical measure is long-term potentiation (LTP): Bliss and Lømo (1973) stimulated the perforant path of the hippocampus and showed that a brief high-frequency burst left the synaptic response persistently enlarged — the first demonstration that experience changes connection strength, and still the reference assay. Its counterpart, long-term depression, completes the ledger of weight change. What is actually measured is simple and instructive: a before-value, an after-value, and the stimulus that separated them.
Structural level. Plasticity is also anatomical: dendritic spines form and prune (two-photon imaging shows spine turnover tracking learning), grey-matter density shifts with training (Maguire’s London taxi-driver hippocampi; Draganski’s juggling studies, measured by voxel-based morphometry), and white-matter tracts reorganize (diffusion tensor imaging). The measure here is a count and a geometry: how many connections, how strong the pathway.
Systems level. TMS-evoked potentials and paired-pulse paradigms measure how excitable a circuit is and how much a conditioning stimulus changes it; fMRI repetition-suppression and representational-similarity analyses measure how a representation drifts with experience.
Molecular level. Markers such as BDNF, immediate-early genes (c-Fos, Arc), and receptor trafficking (AMPA insertion) certify that the machinery of change was engaged — the why behind the before/after.
Behavioral level. Finally, learning curves: savings on relearning (Ebbinghaus), transfer, and the calibration of predictions against outcomes. If no behavior changes, the other measures are epiphenomena.
Three principles fall out of this catalogue. (1) Measure change, not state — every assay is a delta against a recorded baseline. (2) Measure at multiple levels — synaptic strength, structural connectivity, and behavior can disagree, and the disagreement is diagnostic. (3) Attribute the change — a measure of plasticity is worthless without the stimulus (and ideally the prediction error) that produced it.
Why is measuring plasticity important — in the brain?
Because plasticity is where function and pathology meet. The same mechanisms that store a skill store an addiction; the same potentiation that encodes a memory, unconstrained, is epileptogenesis; too little plasticity is rigidity and, clinically, part of what degeneration takes away. Development, rehabilitation after stroke, the action of antidepressants, the closing and reopening of critical periods — all are stories about how much change is possible, where, and under what teaching signal. Medicine can only reason about these because the measures exist: you cannot titrate what you cannot read. And at the level of theory, measured plasticity is what disciplines the field’s claims — “learning occurred” is an assertion; “field EPSP slope increased 40% and persisted 8 weeks” is a result.
Why is it important in our system?
VVG Cortex sits over a firm’s SharePoint estate — in the current deployment, a corpus that emulates a private-equity firm, governed by the same identity system a real one would use — and turns it into a decision memory: episodes, facts, entities, decisions with their expected claims, metrics, risks; consolidation into beliefs; attention over what matters now; valuation against recorded outcomes. Crucially, it learns from use: helpful and unhelpful feedback, reviewer adjudications, immediate re-asks, and realized decision outcomes are converted into a prediction-error signal, and that signal changes a small set of weights — how much attention contested facts receive, how much a given source library is trusted, how wide the retrieval beam opens.
For an enterprise system of record, that sentence is exactly as alarming as it is attractive. A memory that adapts is a memory whose behavior tomorrow differs from its behavior today — and if you cannot say what changed, why, and by how much, you have built an unauditable system and called the problem “learning.” The industry’s default answers — freeze the model, or fine-tune and hope — are the two failure modes the brain avoids: rigidity and unbounded change. The brain’s third way is bounded plasticity under a measured teaching signal, and its scientific tractability comes entirely from the fact that neuroscience learned to measure it. We took both halves: the mechanism and the measurement.
There is also a governance reason specific to agentic AI. Reviewers of such systems now ask a version of the LTP question: show me the before value, the after value, and the stimulus. A system with no fixed prompt and adaptive behavior can only pass that review if change itself is a first-class, recorded object. In Cortex it is.
How Cortex measures its own plasticity
Cortex implements plasticity in three channels, and measures each the way neuroscience measures its counterpart. All three are dark-launchable, evidence-gated, and — this is the invariant — never touch stored evidence or access: facts, episodes, documents, and permissions are not plastic. Only the modulatory weights are.
Recommended by LinkedIn
[ How to Focus to Change Your Brain
Stefano Gaburro, PhD
9 months ago](https://www.linkedin.com/pulse/how-focus-change-your-brain-stefano-gaburro-phd-ccc-dfodf)
[ How High Frequency Oscillations Bridge Neurons and…
Dr. Sarraf
9 months ago](https://www.linkedin.com/pulse/how-high-frequency-oscillations-bridge-neurons-thought-dr-ns-vu8kc)
[ Problem-Focus vs Outcome-Focus: The Neuroscience of…
Annette Tonkin
2 months ago](https://www.linkedin.com/pulse/problem-focus-vs-outcome-focus-neuroscience-why-patients-tonkin-l7epe)
Parametric plasticity — the synaptic-update ledger (the LTP assay)
A small registry defines the only learnable parameters: attention-network weights (watched-subject, goal-relevance, contested-fact, significance, association), the arousal cap on retrieval breadth, and per-source-tier trust. Weekly, a plasticity pass gathers the window’s signals — explicit feedback (attributed to the source tiers of the documents each answer actually cited, which the session’s working memory makes possible), reviewer approve/dismiss decisions on the system’s own detections, recorded decision outcomes — computes a shrunk prediction error per signal key (mean · n/(n+k), so a single vote cannot move anything), and applies at most one bounded step per parameter (|Δ| ≤ 0.05, clamped to the parameter’s range, gated on n ≥ 3 and |PE| ≥ 0.2).
Every applied step is written as a SynapticUpdate node: parameter, old value, new value, delta, prediction error and its evidence count, stated reason, and timestamp. The effective value of any parameter is simply its latest ledger entry (or the default); a reviewer-gated revert appends an entry restoring the default; a single flag returns every reader to defaults instantly while preserving the history. The ledger is therefore Bliss and Lømo’s protocol, industrialized: baseline, stimulus, after-value, persistence — for every weight, forever.
From the ledger we read the parametric metrics:
- Plasticity rate — ledger entries per weekly pass (neural analog: induction frequency). how alive the learning loop is; spikes = the signal changed.
- Drift — cumulative Δ per parameter from default (neural analog: potentiation magnitude). which weights experience has pushed, and how far.
- Off-default fraction — parameters ≠ default / registry size (neural analog: fraction of synapses modified). how much of the learnable surface use has touched.
- Sign consistency — agreement of successive steps per parameter (neural analog: stable LTP vs. LTP/LTD oscillation). stable learning vs. noisy or conflicting signal.
- Evidence per step — the n behind each entry (neural analog: stimulus strength). resistance to noise-chasing.
- Revert rate — reviewer restorations per period (neural analog: homeostatic correction). governance friction — where humans disagreed with the learned value.
Structural plasticity — Hebbian association edges (the spine-count)
When a user marked an answer helpful that cited several documents together, those documents were co-active in a rewarded retrieval. Cortex strengthens a CO_RETRIEVED_WITH edge between them (bounded at 1.0) and decays all such edges weekly — Hebb’s rule with a forgetting term, so the association graph reflects recent, rewarded co-use rather than accumulated coincidence. A nightly replay job — the sleep analog — revisits the most-used documents and lightly reinforces the strongest associations, exactly as hippocampal replay consolidates the day’s most active sequences. The attention system reads these edges as a ranking feature only; an associated document never surfaces on its own authority, and never outside the reader’s permissions.
Structural metrics: edge count, mean and distribution of strengths, formation and decay rates per week, and the size of the connected clusters — the system’s spine density, turnover, and circuit formation, respectively.
Trace plasticity — reconsolidation counters (the reactivation tag)
In the brain, a retrieved memory is briefly labile and is re-stabilized — reconsolidated — with its current relevance. In Cortex, when feedback marks an answer as helpful, the episodes and facts behind its cited documents get last_reactivated_at refreshed and reactivation_count incremented, which (among other things) extends how long their verbatim form is retained before the designed forgetting path reduces them to gist. The counters are the measure: reactivations per window, the age distribution of reactivated traces, and — once forgetting is enabled — retention extended versus retention allowed to lapse. This is the immediate-early-gene stain of the system: which traces the firm’s actual use keeps alive.
The behavioral level — where the three channels must cash out
As in neuroscience, weight change that changes no behavior is noise. Cortex closes the loop behaviorally three ways: benchmark invariance (golden-set questions must keep passing after every weekly pass — plasticity may re-rank, never break); calibration (Brier scoring of expected claims against recorded outcomes as the outcome record grows — the system’s predictions, measured); and the audit line (every answer records the attention gain, the top modulation signals, and the working-memory state that shaped it, so a behavioral change is attributable to the parametric change that caused it). The invariants themselves — permission enforcement, provenance separation, no-verdict rules — are enforced by tests in the deployment pipeline and are outside the plastic surface entirely: the system can learn what to notice, never what to leak.
What impact does this have?
For operating the system. Learning stops being a risk you accept and becomes a quantity you operate. A healthy deployment shows a low steady plasticity rate, drift concentrated in a few interpretable weights, high evidence per step, near-zero reverts, flat benchmarks, and improving calibration. Each deviation is a specific diagnosis: a rate spike means the signal changed (new users, new corpus, or an injection attempt); oscillating sign means conflicting feedback populations; rising reverts means the policy bounds and the humans disagree — a governance conversation, with data. The same numbers give reviewers of agentic systems the before/after/stimulus record they now ask for, and give the operator two safety affordances no fine-tuned model offers: per-parameter reversal and an instant global return to defaults, both without losing the history.
For the science-engineering exchange. Modeling the mechanism forced us to model the measurement, and the measurement is the more transferable artifact. Any adaptive retrieval system — whatever its architecture — can adopt the discipline: enumerate the learnable surface; bound and gate each change; ledger old → new with the teaching signal and its evidence; separate parametric, structural, and trace channels; verify at the behavioral level. That is a definition of auditable machine plasticity, and it is checkable in review rather than arguable in marketing.
What does it add to decision-making for users?
The user-facing dividend is trust with receipts, in four forms.
Answers that adapt for stated reasons. When a partner’s brief ranks a contested fact higher this month than last, the ledger says why: reviewers upheld five challenges in the window, the contested-fact weight moved +0.05, here is the entry. The system’s evolution is explainable to the person it serves — in one query.
A memory that tracks the firm’s actual practice. Hebbian edges and reactivation counters mean the documents and beliefs the firm genuinely uses become easier to retrieve together and stay verbatim longer, while unused material fades toward gist — the memory reorganizes around the firm’s revealed priorities rather than its folder structure, and the reorganization is inspectable.
Judgment that improves measurably. As decision outcomes are recorded, calibration turns “how good is this system’s foresight” into a Brier curve; expected-value and scenario surfaces carry honest sample sizes; and the valuation channel of the prediction error means the weights ultimately answer to what actually happened, not to what was pleasant to hear.
Confidence that adaptation cannot become corruption. The user knows — because it is enforced structurally, not promised — that no document can rewrite the system’s behavior, no weight can move beyond its bounds without a person, no evidence is ever altered by learning, and everything the system has learned can be read, reverted, or switched off. That is what lets a professional rely on an adaptive memory in decisions that matter.
The brain earned our trust as a decision instrument long before we could measure its plasticity — evolution did the auditing. An engineered decision memory gets no such credit, and should not. It earns trust the way the science did: by making change itself observable. That is what the plasticity ledger and its companion measures are for — not to prove the system clever, but to make its learning the most documented thing about it.
VVG Cortex runs on AWS over a Microsoft SharePoint/Entra ID estate; its architecture is described in the companion paper “The Neurocognitive Architecture of VVG Cortex on AWS.” References: Hebb (1949); Bliss & Lømo (1973) J. Physiol.; Bienenstock, Cooper & Munro (1982) J. Neurosci.; Schultz, Dayan & Montague (1997) Science; Turrigiano (2008) Cell; Maguire et al. (2000) PNAS; Draganski et al. (2004) Nature; Nader & Hardt (2009) Nat. Rev. Neurosci.; Wilson & McNaughton (1994) Science.